 alt Hacker News
FLUX 3 Image
Comments
The UX looks amazing and very steerable, congrats to the team for focusing on the interface.
Chats can be awful user interfaces.
Love to see an AI lab outside of US/China releasing good models.
I think we are all waiting for the open weights or local model releases.
Agreed with other comments about the UX. I'm more interested in that than the model itself. Would like to start seeing UI like this where you get to choose the model and compare different models. Can't jump all over the internet to each model developers sandbox just to test their models. Doing it from one place would be nice.
Does anyone know if it can be used to generate accurate frame-by-frame sprite sequences? I found that no image model can do this well (with sufficient fidelity) - neither with one shot (full spritesheet), nor single frame conditioning. It would be great if an imagegen model could do this. What I do now (I use my own tool https://github.com/acatovic/ai-game-studio) is basically generate a reference image, then condition on that image to generate a very short video, then extract and prune frames. Then I get indie-level sprite fidelity about 90% of the time.
This isn't much of a test, but I bought $10 in credits on their playground and generated a test image. Not bad, but it didn't get the accordion keyboard right. Haven't tried editing yet.
It's this a new model or a new ui?
Of note is the OpenRouter endpoint has a promotional 50% discount, which is rare on image models: https://openrouter.ai/black-forest-labs/flux-3-image
So much negativity as usual and so little talk about the product, this is pretty impressive, well done, it seems to be filling decently a gap that everyone that has worked enough generating images with AI has faced.
For a moment I was confused that this was a release of a new stable diffusion. What happened with Stable Diffusion?
https://news.ycombinator.com/item?id=49031796
What's new from the last post? GA?
I like the interface; very useful for some use cases that would otherwise be quite frustrating. Dislike that it's yet another platform held back by arbitrary moderation. You can't make a bicycle for the mind that locks if you try to ride it in the wrong direction.
That sort of steering ability that has been possible with the latest Gemini releases has been nice to work with over previous generations. It’s great to see this improve on the platform with declarative controls built into the API and coming soon as an open model.
I shouldn't have to scroll all the way down, click to use the thing, then fumble around to figure out what this does. It should be clear at the top of the first page (so I know right away that I don't need this).
Yes, you can do that with AI now.
looks cool, eternally greatful these models are marked for open weight releases. Pretty excited
Tried Flux 3 on a tiny subjective image benchmark I’m calling One Knee Wonder.
Exact prompt:
Generate a photorealistic image of M81 urban BDU camouflage cargo trousers, shown by themselves. One trouser leg should be posed with the knee lifted 30° from vertical.
Accurate reproduction of the M81 urban camouflage pattern is critical. Match its colors, shapes, scale, distribution, and overall appearance as faithfully as possible.
No person, other clothing, or props.
Ground truth swatch: https://commons.wikimedia.org/wiki/File:US_City_Camo_(M81_Ur...

Gemini 3 Pro Image (stronger pattern): https://i.postimg.cc/bZNQYYjx/2026-10-02-google-gemini-3-pro... Flux 3 (this run): https://i.postimg.cc/Xr7wNN0H/2026-10-02-black-forest-labs-f...
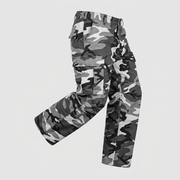
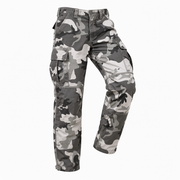
Flux 3 gets greyscale urban-ish trousers and a lifted knee, but the blotches aren’t real M81 Urban — softer / wrong geometry vs the swatch. Not the worst I’ve seen on this prompt; clearly behind the Gemini 3 Pro Image example above on pattern.
Curious what other models do on the same prompt.
Unrelated to the flux images used for floppy disk archiving? Sigh.
One of the things they seem to be emphasizing here is the UX around being able to place specific elements where you want them in an image. If the positions of the components in the overall composition are very important, this seems to make that a lot easier and kind of reminds me of InvokeAI.
Ideogram V4, an open-weight model released back in June can also do this [1], but you have to use a relatively cumbersome JSON structure to describe all the different bounding boxes. So it’s definitely a bit of a hassle.
I'll probably be waiting until it goes open-weight (hopefully soon) like they did with Flux.2 / Klein.
[1] - https://docs.ideogram.ai/using-ideogram/getting-started/prom...